The Eval Set Contamination Problem: Why Your Production Traffic Leaks Into Your Test Set and Inflates Every Score
Your eval scores keep climbing and your model looks better every sprint -- but production quality is flat, and users are not any happier. Somewhere between logging real traffic and building your golden set, the two ponds started sharing water. Once production examples leak into the set you grade against, every number you trust becomes a measurement of memorization, not capability. Eval set contamination is the quiet reason your benchmarks and your users disagree.
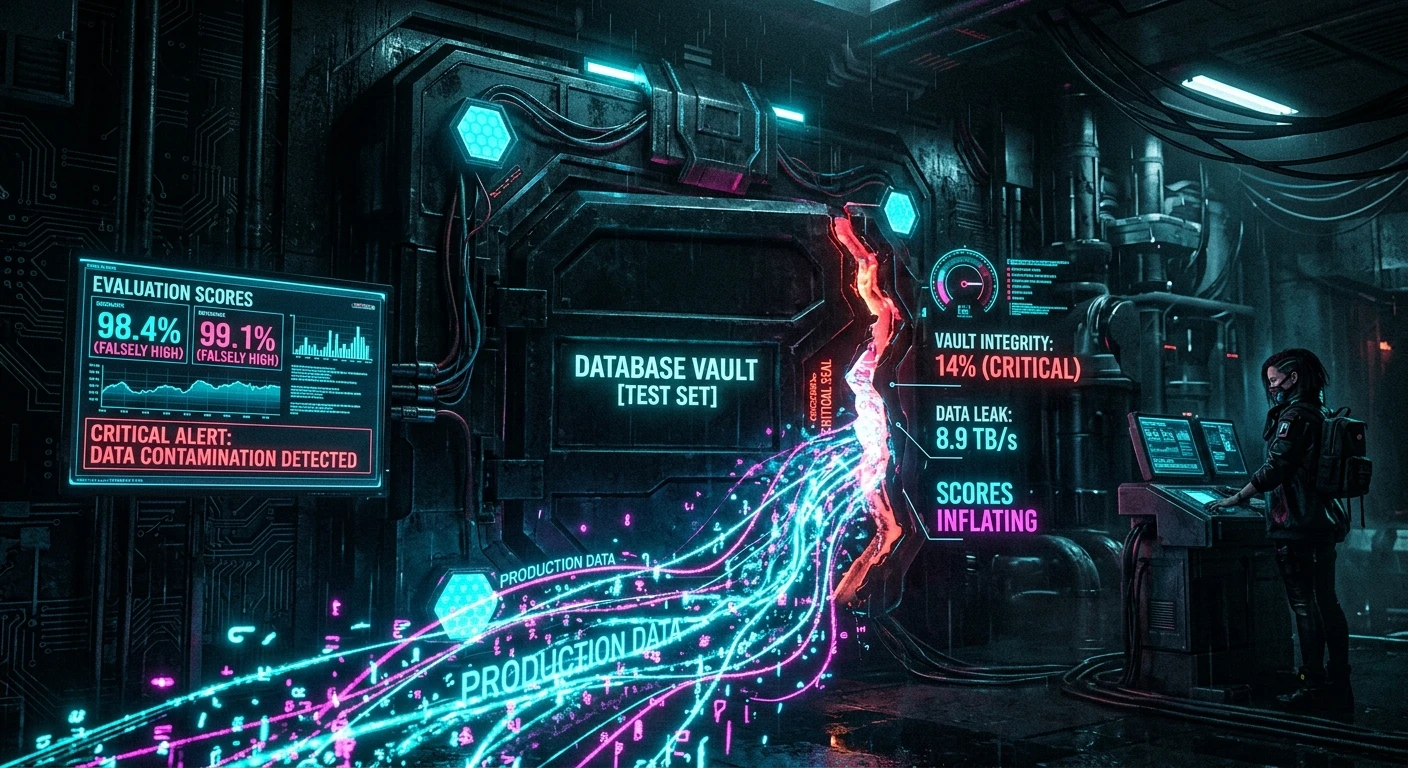
The Two Ponds That Started Sharing Water
Every serious AI team eventually builds a golden eval set: a curated collection of inputs and expected outputs that you grade every model, prompt, and pipeline change against. It is supposed to be the fixed ruler -- the thing that does not move, so that when your score goes up you can trust that the system got better. And for a while it works. Then, quietly, the ruler starts stretching. Your eval numbers climb sprint after sprint, the dashboards glow green, and yet production quality is flat and users are no happier than they were three releases ago.
The usual culprit is not a bad model or a bad metric. It is contamination: production traffic has leaked into the set you grade against. The moment examples your system has already seen -- or examples drawn from the same distribution it was tuned on -- end up inside your test set, you stop measuring capability and start measuring memorization. Eval set contamination is the silent reason your benchmarks and your users have stopped agreeing, and it is far more common than teams admit because every path that leads to it feels like good engineering hygiene.
How Clean Sets Get Dirty
Contamination rarely arrives as one obvious mistake. It seeps in through reasonable-looking pipes.
The feedback-to-fixture pipeline. You log production failures, triage them, and -- sensibly -- add the hard cases to your eval set so you never regress on them. But if those same logged examples also feed your prompt tuning, few-shot selection, or fine-tuning data, the set is no longer independent. You are grading the system on examples it was optimized against. The score goes up because the system memorized the answer, not because it generalizes. This is the classic overfitting-to-the-test-set failure, and it is invisible without the discipline of eval-driven development that treats the test set as a protected asset.
Near-duplicate leakage. Even when you never copy an example verbatim, production traffic is full of near-duplicates: the same question phrased three ways, the same document re-uploaded, the same intent with a different name. Exact-match dedup misses all of it, so semantically identical items land on both sides of the wall. Your model looks brilliant on the eval because it saw the twin in training, and the leak is undetectable unless you dedup on embeddings, not strings.
Timestamp collapse. Eval sets are supposed to represent a frozen moment, but production distributions drift. When you refresh your golden set from recent traffic without segregating it from the traffic that trained the current model, you fold two different points in time into one, the same class of confound as prompt version skew, where an A/B test compares two prompts that were never actually live together.
Silent drift in what "correct" means. Sometimes the inputs stay clean but the labels rot. As the product changes, yesterday's correct answer becomes today's wrong one, and a stale golden output starts rewarding the wrong behavior. Nothing errors; the number just stops meaning what you think it means -- the defining signature of silent failure in agentic AI success metrics.
Why This Is So Dangerous
A contaminated eval is worse than no eval, because it manufactures confidence in exactly the direction that hurts you. You ship changes that improve the memorized score and degrade real performance, and your instrumentation applauds the whole way down. The gap between the model you evaluated and the one users actually experience widens silently, and every stakeholder decision -- to ship, to expand scope, to trust the agent with a higher-stakes action -- is made on an inflated number.
The damage compounds because contamination is self-reinforcing. Once a leaked example is in the set, it stays there across many release cycles, quietly inflating every future score and anchoring the team to a baseline that was never real. And when someone finally notices that production and eval disagree, there is usually no way to reconstruct which examples leaked, when, or how -- the exact traceability failure that makes model provenance and decision attribution impossible in production. Without provenance on your eval data, you cannot even prove the ruler is bent, let alone straighten it.
How to Keep the Ponds Separate
Contamination is a systems problem, not a labeling problem, and it has to be engineered out at the boundaries.
Enforce a hard train/eval firewall with provenance tags. Every example must carry an immutable origin tag: what it was used for, when it entered the corpus, and which side of the wall it lives on. An example tagged "eval" can never be used for tuning, and the pipeline must refuse to cross the line. This is a boundary guarantee, and it belongs in code as a data contract enforced at the seams of the pipeline, not in a team norm that erodes under deadline pressure.
Dedup semantically across the wall, not just within it. Before any example joins the training corpus, check it against the eval set with embedding-based similarity, and reject or quarantine near-duplicates. String matching is not enough; the leaks that matter are paraphrases.
Freeze eval sets and version them like code. A golden set should be immutable once cut, with a new version created deliberately when you refresh it -- never edited in place. Track which model was evaluated against which eval version, so a bent ruler can be caught by comparing versions. Ungoverned, ever-mutating eval assets are just another instance of configuration drift silently reshaping system behavior.
Hold out a sealed, never-tuned canary set. Keep a slice of eval data that is used for nothing but final measurement -- never inspected during development, never mined for hard cases. A large gap between your working eval score and your sealed canary score is the smoking gun of contamination, and it turns an invisible leak into a visible alarm. Wiring that alarm into your dashboards is exactly the kind of observability that separates monitored AI systems from hopeful ones.
The Takeaway
An eval set only tells you the truth for as long as it stays independent of everything you optimize. The instant production traffic leaks in -- through feedback pipelines, near-duplicates, timestamp collapse, or rotting labels -- your benchmark quietly converts from a measure of capability into a measure of memorization, and it will cheer for every change that makes your users worse off. Tag provenance, firewall train from eval, dedup semantically, freeze and version your sets, and seal a canary you never touch. The goal is not a higher score. It is a score you can actually believe when it is time to ship.
Bigyan Analytics builds the evaluation infrastructure that keeps enterprise AI benchmarks honest -- provenance-tagged data, sealed canary sets, and contamination detection wired into CI. Book a working session to audit whether your eval scores are measuring capability or memorization.
Founder & Principal Architect
Ready to explore AI for your organization?
Schedule a free consultation to discuss your AI goals and challenges.
Book Free Consultation